About
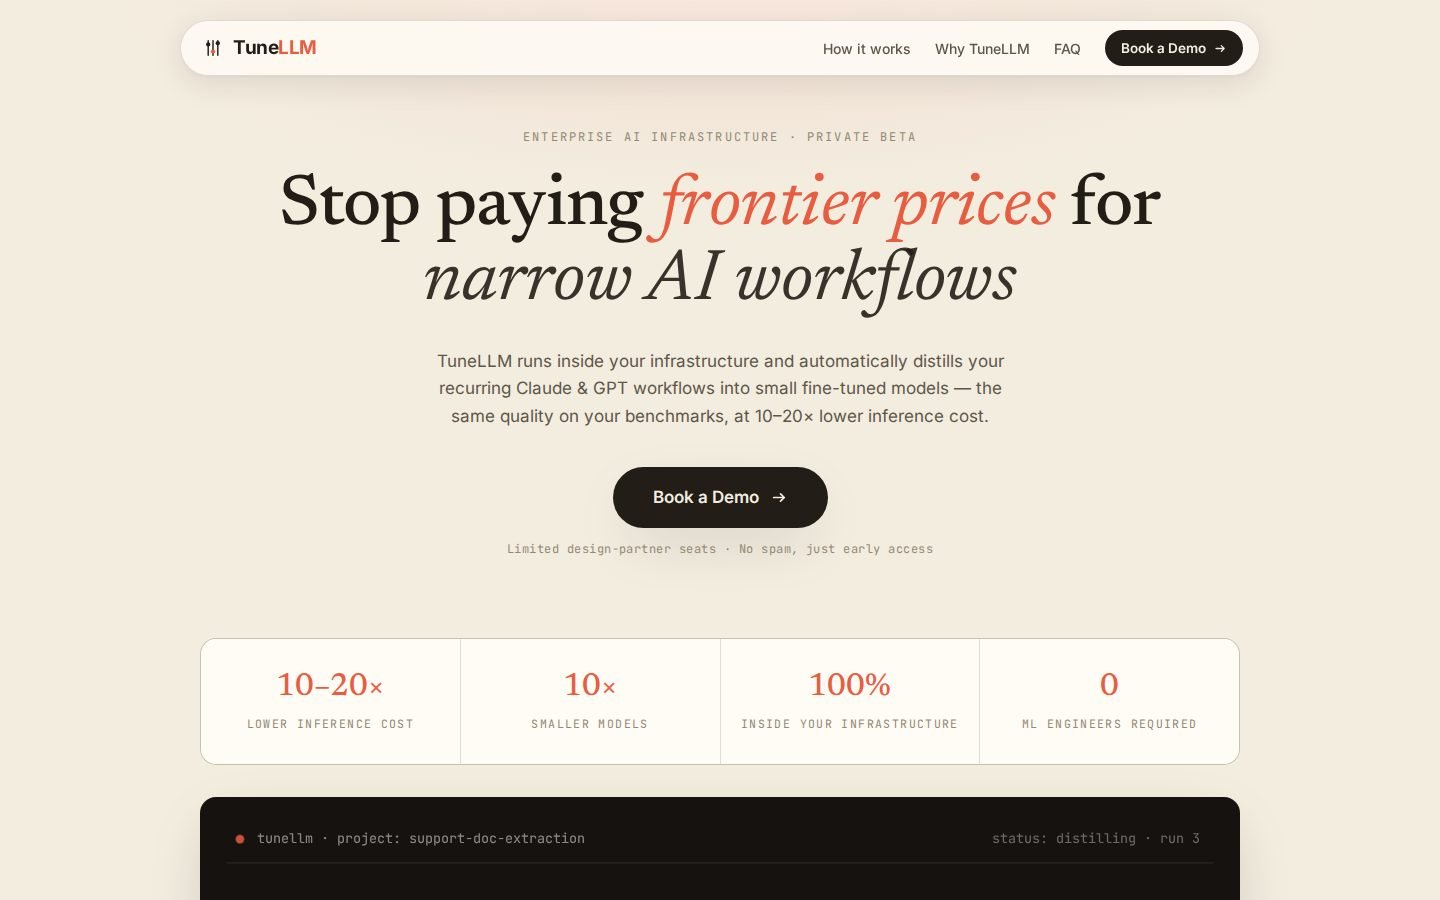
TuneLLM reduces inference costs for AI workflows by automatically distilling large frontier models into smaller, fine-tuned models that run inside the user's own infrastructure. Instead of paying premium rates for generalist models like Claude or GPT for narrow, high-volume tasks such as translation, document parsing, or classification, users can proxy their existing API calls through TuneLLM. The system captures the data, trains a smaller model on the specific workflow, and provides a benchmark-gated switch to the distilled model, claiming a 10–20x reduction in cost while maintaining quality. The platform requires no ML engineering expertise and keeps all data and model weights within the user's private cloud or on-premise environment.
Key Features
- Automated distillation of frontier models (Claude, GPT) into smaller models
- Runs 100% inside user's infrastructure (private cloud or on-premise)
- Zero ML engineering required; uses existing system prompts
- Benchmark-gated switching to ensure quality matches the original model
- Supports narrow workflows like translation, tagging, and summarization
What Makes It Different
Unlike general AI API providers, TuneLLM focuses specifically on cost reduction for existing high-volume workflows by creating custom, smaller models that live in the user's own environment, eliminating the need for an internal ML team.
Pricing
See website for pricing
Discover More Indie Products
Find amazing alternatives to big SaaS tools built by indie developers